

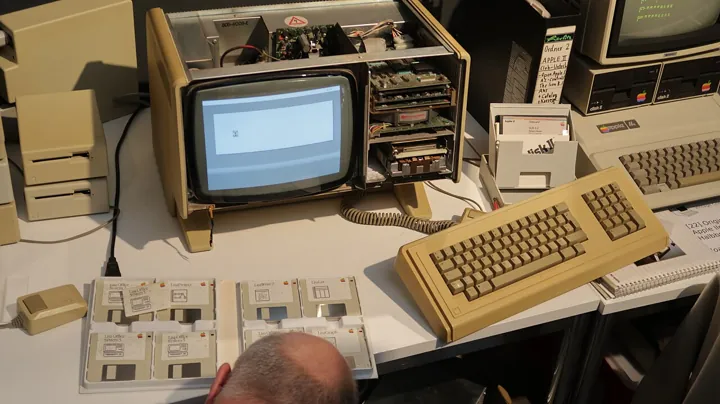
- Description
- An Apple Lisa being repaired
- Source
- stiefkind · original page
- Licence
- CC0 Public domain
 The Goodhart effect (visibility bias)
When a measure becomes the target, people optimize the measure more than the outcome it was meant to reflect.
In brief
- What: an indicator chosen to reflect an outcome gets distorted when used to steer or reward; we also overvalue what is measurable at the expense of everything else.
- Why: everyone optimizes what is measured and rewarded; the indicator and the outcome drift apart.
- Detect: the indicator improves while the real experience stagnates or degrades; behaviors done “for the number.”
- Avoid: several cross-checked indicators, a balancing indicator, measuring to learn rather than punish, qualitative review, periodic change.
Definition#
 Fictitious illustration
 Fictitious illustration
 Fictitious illustration
The Goodhart law is named after British economist Charles Goodhart, who stated it in 1975 regarding monetary policy: any observed statistical regularity tends to collapse once it is used for control. Anthropologist Marilyn Strathern (1997) gave the now-famous wording: “when a measure becomes a target, it ceases to be a good measure”. Psychologist Donald Campbell had stated a related idea in 1976 (text published in 1979): the more a social indicator is used for decision-making, the more it is exposed to pressures that corrupt it (Campbell law).
This is not a cognitive bias in the strict sense. It is a regularity of incentive systems, involving conscious strategies (cheating, gaming) as much as judgment distortions. It is grouped here with biases because it relies on a visibility bias (we value what can be counted and seen: the “streetlight effect” or the McNamara fallacy, which consists of keeping only what can be quantified) and because it leads to decisions distorted by what we chose to display.
The mechanism#
- A measure is a proxy. We measure what is easy (lines of code, tickets closed, calls handled) to approximate what matters (value, quality, satisfaction). The link between the two is statistical, so it is fragile.
- When you reward the measure, you shift effort. Everyone optimizes the indicator, sometimes in good faith, sometimes by gaming it: inflate, split, shift, exclude.
- The unmeasured disappears. What is not on the dashboard (code quality, mutual help, debt, maintenance) is sacrificed for what is.
- The link breaks. Once the target is reached through these means, the indicator is no longer correlated with the original outcome: the dashboard is green, reality is not.
It is often said that in Delhi, under British administration, a bounty on dead cobras led residents to breed them, and that removing the bounty led to the snakes being released. This story is not established: there is no known contemporary source, and it was popularized by German economist Horst Siebert, who named it the cobra effect (2001). The documented comparable episode is Hanoi in 1902, in French Indochina: rat hunters were paid per tail turned in, and historian Michael Vann showed that some cut off the tail and released the animal so it could reproduce.
Where you encounter it#
In project management#
- Lines of code: measuring a developer's output by lines written encourages verbose code and discourages refactoring that removes code (see case below).
- Velocity: when a team's velocity (story points per iteration) becomes a target or is used to compare teams, estimates get inflated and velocity rises without any increase in delivered value. This is a commonly observed phenomenon, not documented here with a specific study.
- Test coverage: requiring a coverage percentage produces tests that execute code without checking anything.
- Tickets closed, resolution times: people close quickly, reopen tickets, split one into two so counters rise, or classify a defect as an “improvement.”
- Schedule and budget compliance: if deviation from plan is punished, numbers are padded at project start (hidden buffers) or remaining work is underestimated until the end.
- Contractual availability: a 99.9% service indicator encourages declaring as an “incident” only what falls within the measured scope.
In management#
- Individual goals and bonuses: the sales rep targeting sales volume gives discounts or pushes poorly targeted customers; support targeting average handling time hangs up quickly.
- Dashboards: what appears there becomes the team's reality; what does not appear there (helping colleagues, documentation, mentoring) is neither done nor recognized.
- Annual evaluation: the employee knows which numbers matter and works for them; the one who creates unmeasured value is disadvantaged.
- Satisfaction surveys: when the score affects the bonus, people beg customers to give a “10” or cherry-pick respondents.
- Hours and presence: time present measures only part of effort; it encourages visibility more than outcomes.
A dashboard indicator becomes the target: “tickets closed per week” goes up, quality goes down. Always publish a balancing indicator next to it (for example, the reopening rate), change measures periodically to prevent drift, and date each indicator definition in the semantic model.
Famous cases#
Apple Lisa: the engineer who wrote “−2000 lines” 1982#
Bias at play: measuring productivity by lines of code (Goodhart’s law, visibility bias).
What happened. According to Andy Hertzfeld’s account, published on folklore.org, Lisa software team managers decided, in early 1982, to track each engineer’s work by the number of lines of code written, using a weekly form. Bill Atkinson, author of QuickDraw, then rewrote the region calculation routine, made it about six times faster and more flexible, and reduced it by about 2,000 lines. On the form, he wrote “−2000.” Managers stopped asking him to fill out the form.
What this illustrates
The metric made deleting code, which is progress, look like a setback. The anecdote is known through direct testimony, not through a contemporary document: treat it as an illustration, not as a measurement. The conclusion applies to all volume indicators: what we count is not what we want, and sometimes the best work is the work that lowers the counter.
Wells Fargo: accounts opened to hit quota 2011-2016#
Bias at play: Goodhart’s law (sales target per customer, pressure from bonuses and sanctions).
What happened. U.S. bank Wells Fargo set cross-selling targets for its branches: the number of products per customer (the internal target mentioned was eight). Under quota pressure, employees opened deposit accounts and credit cards without customer consent, sometimes by creating fake email addresses. On September 8, 2016, the Consumer Financial Protection Bureau, the Office of the Comptroller of the Currency, and the Los Angeles City Attorney announced fines totaling $185 million, and the bank’s analysis covered about two million accounts; a later review expanded the scope. About 5,300 employees had been fired for these practices over several years.
September 2016 fines
Loading the chart…
View the data
| CFPB | OCC | Los Angeles | |
|---|---|---|---|
| CFPB | 100 | - | - |
| OCC | - | 35 | - |
| City of Los Angeles | - | - | 50 |
What this illustrates
The indicator (products per customer) was supposed to reflect the customer relationship. Once it became a quota with sanctions attached, it was met through accounts that made no sense for the customer. The stronger the pressure on the indicator, the more it gets gamed. The same pattern appears at smaller scale as soon as a number drives a bonus or a sanction.
Hanoi, 1902: rat tails 1902#
Bias at play: bonus tied to a gameable indicator (documented “cobra effect”).
What happened. The French colonial administration, aiming to eliminate rats from Hanoi’s sewers, hired hunters paid per tail turned in (which avoided having to inspect carcasses). Archives studied by Michael Vann show rats captured, stripped of their tails, then released to breed, and rat farms. The operation was abandoned. The Hanoi episode is documented; the Delhi cobra story is not (see the box above).
What this illustrates
A bounty on the proof item (the tail) rather than on the outcome (fewer rats) invites people to produce the proof item. If evidence can be manufactured cheaply, it will be.
The Pinel program: when the tax benefit becomes the goal (France) 2014-2024#
Bias at play: Goodhart’s law (zoning and tax reduction as targets).
What happened. Created on September 1, 2014 to replace the Duflot program, Pinel grants a tax reduction to individuals who buy a new home (or renovate one) and rent it out, under rent and income caps, in so-called tight-market zones (A bis, A, B1) under A/B/C zoning. The stated goal is to house households struggling to access housing in these zones. In its September 2024 evaluation, the Cour des comptes notes that the tax benefit is the main motivation for more than 80% of surveyed investors, that the program was not designed to measure growth in intermediate housing supply due to the lack of a numerical target, and that more than half of units are in zone B1 (55.6%) rather than in the tightest zones. It also notes, for the “Pinel breton” experiment, that 40 of the 58 selected municipalities have a rent cap above market rent. It concludes that the program only imperfectly meets its construction and renovation goals in tight markets.
Where the bias appears. Goodhart’s law describes what happens when a measure becomes a target: it stops measuring well what it was supposed to measure. Here, a municipality’s inclusion in a tight zone is used as a proxy for affordable housing need, and the tax reduction is used as leverage; investors and operators optimize tax eligibility (zone, cap, after-tax yield) more than the increase of affordable housing where pressure is highest. What is established is the Court’s numerical findings; what is our interpretation is to classify them under the Goodhart effect, because the Court speaks of insufficient effectiveness and imperfect targeting, not of a Goodhart effect. Context matters: investors respond to a legal incentive, and zoning also serves other purposes (rent control, tax on vacant housing). Level of evidence: accepted, not proven. The facts are established by an official report, but the cognitive mechanism or gaming of the indicator is not demonstrated.
What this illustrates
When assistance depends on a proxy indicator (a zone, a cap), check that this indicator still matches the real objective, and set a numerical target from the start that can be measured.
Detection signals#
- The indicator improves while complaints, returns, or technical debt increase.
- “For-the-number” behaviors: splitting work to count it twice, closing then reopening, pushing items to period-end.
- People explain how to make the number go up before saying what should actually be done.
- Useful but unmeasured work (documentation, mutual help, refactoring) disappears.
- A target is met with suspicious regularity, with no natural variation, or always just above the threshold.
- The number has an owner whose bonus or reputation depends on it.
Avoidance reflexes#
- State what the measure is supposed to reflect. Before choosing an indicator, write down the intended outcome (value, quality, satisfaction) and how the indicator could be gamed.
- Cross-check multiple indicators. One volume indicator, one quality indicator, one satisfaction indicator: to inflate one, you have to degrade another, and it shows.
- Add a balancing indicator. Speed with defect rate, quantity with rework, sales with cancellations.
- Measure to learn, not to sanction. A number used to understand is gamed less than a number used to punish or reward. Avoid comparing teams by velocity.
- Decouple the number from the bonus. The more direct and strong the link, the more the number will be distorted.
- Complement with qualitative judgment. Code review, customer interview, demo: perspectives that do not reduce to a number.
- Audit and refresh. Sample-check the gap between the number and field reality, and change the measure when people start gaming it.
- Reward raising bad news. A system where red is sanctioned produces dashboards that are always green.
With AI: detect, fix, mitigate#
AI helps spot divergences between indicators, imagine ways to game them before rollout, and cross-check data. But it also speeds up Goodhart's law: anything that becomes a target (code volume, number of tickets, lines of documentation) can be produced in large quantities by generative tools. Measuring AI usage by output volume is a pitfall.
Detect#
- Spot divergence between indicators that should move together (velocity goes up, defects go up).
- Detect gaming patterns in data: end-of-period spikes, split tickets, values just above the threshold.
- Read verbatims to capture what the number does not say.
Fix#
- For a given objective, propose complementary indicators and a balancing indicator.
- Simulate “how to game this indicator” before adopting it (adversarial review).
- Help define precisely what the indicator should reflect and its usage limits.
Mitigate#
- Produce a cross-indicator dashboard that places each indicator next to its counterweight.
- Summarize qualitative feedback (reviews, tickets, interviews) to read alongside the numbers.
- Periodically review the relevance of the selected indicators.
Prompts to integrate into your practices#
1. How can this indicator be gamed?. Before adopting an indicator, an objective, or a bonus.
We are considering the following indicator: [precise definition, period, scope] to reflect [the actual intended outcome].
1. List ten ways, legitimate or not, to increase this indicator without improving the intended outcome.
2. For each one, indicate what observable signal would make it detectable.
3. Propose two or three complementary indicators, including one balancing indicator, so that inflating one degrades another.
4. Say whether this indicator should be used to steer, to learn, or to reward, and why.
Do not assume bad faith from teams: describe mechanisms, not people.
2. Audit of an existing dashboard. On a dashboard and its data, without personal data.
Here is a team dashboard and the history of its indicators: [definitions, values by period].
1. For each indicator, state the outcome it is supposed to reflect and what it does not measure.
2. Identify pairs of indicators that should move together but diverge.
3. Identify suspicious patterns: end-of-period spikes, values clustered just above a threshold, definition changes.
4. List what matters to the team that is not measured.
For each finding, say whether the data proves it or only suggests it.
How to integrate them#
- When creating an indicator: prompt 1 acts as a “devil's advocate”; record its answers in the indicator definition.
- Every quarter: prompt 2 serves as a dashboard review, with the team.
- With AI itself: do not measure its contribution by volume (lines, tickets, pages) but by downstream value and observed quality.
Precautions#
- AI can invent quantified “good practices” or benchmarks: require sources and verify them.
- Do not provide individual performance data to an unauthorized tool; anonymize.
- An indicator produced from automated analysis also becomes a target: do not create one more without asking how it will be played.
- Workarounds imagined by AI are only hypotheses: test them against field reality.
Limitations#
- The law is not a theorem: measurement is not the problem. Many indicators work very well, especially when used to understand rather than to reward. Risk increases with what is at stake (bonus, sanction, ranking).
- Wordings vary: Goodhart talks about a statistical regularity that collapses when managed, Strathern about a measure that becomes a target, Campbell about corrupted social indicators. These are empirical laws, not universal truths.
- Several famous anecdotes are stories, not records: Delhi's cobra effect is an unverified legend, the Lisa anecdote relies on testimony; only Hanoi and Wells Fargo are solidly documented.
- Giving up indicators is another mistake: without measurement, you fall back on impression and visibility (see The mere-exposure effect).
- Velocity as an inflated target is a widespread observation in agile teams, with no quantitative study cited here on the topic.
Sources and verification#
- Goodhart (1975), “Problems of monetary management: The U.K. experience,” in Papers in Monetary Economics, vol. 1, Reserve Bank of Australia — the original statement, about British monetary policy.
- Strathern (1997), ““Improving ratings”: Audit in the British University system,” European Review, 5(3), p. 305-321 — the wording “when a measure becomes a target, it ceases to be a good measure.”
- Campbell (1979), “Assessing the impact of planned social change,” Evaluation and Program Planning — Campbell's law.
- Muller (2018), The Tyranny of Metrics, Princeton University Press — the abuse of measurement in organizations.
- Hertzfeld, “−2000 Lines Of Code,” folklore.org — the Apple Lisa (1982) story.
- Consumer Financial Protection Bureau (September 8, 2016), press release on Wells Fargo fines — amounts and number of accounts (estimates at the time).
- Vann (2003), “Of rats, rice, and race: The Great Hanoi Rat Massacre, an episode in French colonial history,” French Colonial History, 4 — the rat tails episode.
- Siebert (2001), Der Kobra-Effekt, Deutsche Verlags-Anstalt — origin of the name, based on the Delhi cobra story (unverified).
- Cour des comptes (2024), “Tax assistance for Pinel rental investment,” thematic public report (public policy evaluation) — quantifies the cost, investors' tax motivation, distribution by zone and income profile, and concludes that objectives were only imperfectly achieved.
