

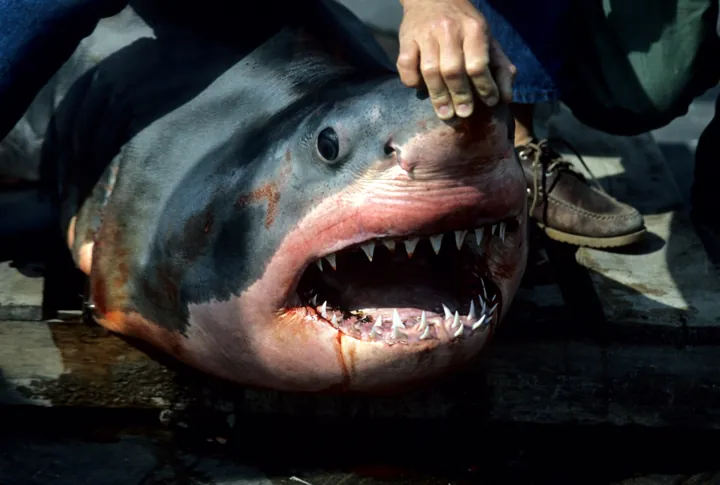
- Description
- Tête d'un grand requin blanc, gueule ouverte sur ses rangées de dents
- Source
- Dr. Dwayne Meadows, NOAA/NMFS/OPR · original page
- Licence
- PD Public domain
 Availability heuristic
What we remember without effort seems frequent to us; what is discreet or old seems rare, even when it is not.
In brief
- What: the probability of an event is judged by how easily examples come to mind.
- Why: what is recent, spectacular or personally experienced is remembered better, without being more frequent.
- Detect: priorities follow the latest incident or the latest news rather than the data.
- Avoid: look at frequency figures, build the risk list in a cool moment, compare against forgotten cases.
Definition#
 Illustration inspired by the person
 Fictitious illustration
 Fictitious illustration
The availability heuristic is a mental shortcut: to estimate the frequency or probability of an event, we look at how easily examples come to mind. When the cases that are easy to recall are also the most frequent, the rule works. When the ease comes from something else (recency, emotion, media coverage, personal experience), it produces the availability bias.
It was described by Amos Tversky and Daniel Kahneman in 1973 in "Availability: A heuristic for judging frequency and probability," then incorporated into their 1974 overview of judgment heuristics.
The mechanism#
- Substituting an easy question for a hard one. "What is the probability of this incident?" becomes "can I remember one?" The second is answered quickly, and the answer is taken for the first.
- What stands out is remembered better. Recent, spectacular, emotionally charged events, or ones we experienced ourselves, are easier to call up than frequent but mundane ones.
- The media and internal stories do the selecting. What gets told (the production incident, the big client lost, the data leak in the press) is over-represented compared with what does not (minor outages, the thousands of uneventful deployments).
- Ease of imagination. Tversky and Kahneman note that probability is also judged by how easily we imagine a scenario. A risk we can describe in detail seems more probable than one we have no picture of.
In one experiment, participants are asked whether, in an English text, more words begin with the letter K or have it as their third letter (and likewise for R, L, N, V). Most answer "begins with," whereas these letters are more frequent in third position: it is simply easier to retrieve words by their first letter. In another, participants are read lists of people's names, some of them famous: they judge the sex whose names are the most famous to be more numerous, because those names are easier to recall.
Studies by Lichtenstein, Slovic and colleagues (1978) showed the same pattern for causes of death: we overestimate spectacular, heavily publicized deaths (plane crashes, homicides, tornadoes) and underestimate discreet but frequent causes (diabetes, heart disease, asthma).
What we remember versus what is frequent (typical pattern, illustrative)
Loading the chart…
View the data
| Actual frequency | Perceived frequency | |
|---|---|---|
| Spectacular cause (rare) | 20 | 70 |
| Discreet cause (frequent) | 80 | 30 |
Where we encounter it#
In project management#
- Risk management: the risk list repeats those of the last project, or the last incident, rather than those the data suggest. The "classic" but discreet risk (a key person resigning, scope creep) is forgotten.
- Post-mortems: recent and vivid events dominate the retrospective; the first months of the project are forgotten (see the recency effect).
- Prioritizing security or testing: after a publicized breach, effort goes there, at the expense of more frequent risks.
- Estimating: we estimate from the last similar project we have in mind, and not from the series of past projects.
- Production review: "it crashes all the time" after two outages in a week; or, conversely, "we've never had a problem" because we don't remember any.
- Technology choice: we pick the technology for which we have read recent, enthusiastic experience reports.
In management#
- Annual evaluation: a year is judged on the last few months, or on the standout incident, rather than on all the facts.
- Hiring: we generalize from one experienced case ("people from that school don't last").
- Human resources decisions: after a string of resignations, we see a general retention problem; after a long calm period, we no longer see one.
- Budget allocation: we fund this year's crisis, not the most probable risk.
Famous cases#
After September 11: taking the car rather than the plane 2001-2002#
Bias at play: availability (spectacular risk), aversion to “dread risk.”
What happened. After the attacks, air traffic in the United States dropped sharply and a large number of travelers chose the car. The psychologist Gerd Gigerenzer compared the number of deaths on American roads with that of previous years: in an article published in 2004, he estimated the excess of road deaths in the last quarter of 2001 at 353 (more than the passengers of the four hijacked planes); in a 2006 study, he put the excess over the following twelve months at 1,595. He interprets it as the effect of a spectacular, memorable risk that took precedence over a mundane risk, far higher per mile: that of the road.
What this illustrates
The images of September 11 made the risk of flying extremely available, and the risk of the road invisible. The causal attribution remains debated (other factors, such as the economy or the weather, may have played a part: the estimate is a statistical inference, not a direct measurement). Keep the mechanism in mind: a vivid risk mobilizes energy, and that energy is missing for more probable risks. This is the logic behind many IT security or testing trade-offs after an incident.
Causes of death: what we overestimate, what we forget 1978#
Bias at play: availability (overestimating spectacular causes).
Sarah Lichtenstein, Paul Slovic, Baruch Fischhoff, Mark Layman and Barbara Combs (1978) asked participants to estimate the frequency of many causes of death in the United States (diseases, accidents, homicides, natural disasters) and compared them with official statistics. The estimates follow the true order of frequencies, but in a flattened way: rare, spectacular causes (tornadoes, floods, homicides) are overestimated, while frequent, unremarkable causes (diabetes, heart disease, asthma) are underestimated. The authors link the gap to media coverage and personal experience.
What this illustrates
Even with reasonable participants, the memory of striking events distorts perceived frequency. A team that sets its priorities "by gut feeling" reproduces this pattern: incidents that made noise weigh more than silent but constant outages.
Warning signs#
- "I remember a case where…" as the only argument for judging probability.
- This week's priorities follow the latest incident or the latest news.
- The risk list of a new project is a copy of the previous one's.
- Discussions mention personal or reported anecdotes, rarely figures.
- A risk with no lived example is called "theoretical."
- A security or testing decision is made right after a publicized incident.
- No one can say how many times an event has actually occurred.
Avoidance reflexes#
- Move from anecdote to figure. "How many times has this happened over the last twenty-four months?" Incident, ticket or operations logs are better than memory.
- Build the risk list in a cool moment. Away from any recent incident, with a varied group of participants and a list of categories to go through, so as not to start from the last case experienced. The pre-mortem helps imagine scenarios that are not spontaneously available.
- Look for forgotten cases. "Which incidents or projects happened to us before the last six months?" Keep a written history of incidents and decisions.
- Use a reference class. Look at statistics from projects, incidents or outages in comparable situations, rather than your immediate experience.
- Distinguish severity from frequency. A vivid risk is often serious; that does not make it probable. Evaluate both, separately.
- Beware of the "recent." After an incident, wait before redirecting priorities: ask what it reveals about the whole, not just about itself.
- Put numbers on silent risks. Measure what has no face (small outages, accumulated delays, lost time), so that it becomes visible.
- Vary the sources. Ask people with different experiences (operations, support, business), because everyone remembers what they lived through.
With AI: detect, remedy, mitigate#
AI is useful for aggregating a history (incident logs, tickets, minutes) and extracting frequencies, where a team's memory mainly retains the standout incidents. It does not replace the quality of the data; and it has its own bias toward the examples most present in its training data.
Detect#
- Compare the actual frequency of incidents in a history with the one teams cite.
- Spot, in minutes, arguments based on a single anecdote.
- Flag risks missing from a list, relative to standard categories.
Fix#
- Produce a quantified summary of the history: types, frequencies, durations, trends.
- Propose a risk list by category, to be completed in a cool moment.
- Draft the questions that bring a discussion back to the data.
Mitigate#
- Have the AI review a risk list before the meeting, to add the forgotten ones.
- Ask for scenarios outside the team's experience, to widen what is available.
- Have it produce a regular report of frequencies, which makes silent risks visible.
Prompts to build into your routines#
1. Actual frequencies from a history. On an anonymized export of incidents or tickets.
Here is the history of incidents or tickets for the last twelve (or twenty-four) months: [export].
1. Classify them by category and indicate, for each category, the count, the cumulative duration of impact and the trend.
2. Say which categories weighed the most in time or cost, and which made the most noise but did little damage, if the data allows.
3. Indicate what the data does not allow us to state.
Do not invent any value and flag any assumption.
2. Complete a risk list in a cool moment. Before a risk review, to get beyond the last incident.
Here is the list of risks our team has retained for [project]: [list]. It has probably been influenced by our recent incidents.
1. Go through these categories: technical, schedule, scope, human resources, suppliers, security, operations, regulatory, funding, organization, and propose for each the common risks missing from my list.
2. For each risk added, give an early warning sign we could monitor.
3. Flag those on my list that seem to rest on a single recent event.
Do not give any numerical probability: it will be up to the team to establish them from its data.
How to build them in#
- Every quarter: prompt 1 produces a quantified summary of incidents, to compare with the team's gut feeling.
- Before a risk review: prompt 2 completes the list, before the discussion starts from the last incident.
- After a striking incident: compare it with the history first before redirecting priorities.
Precautions#
- AI has no access to your reality: it knows only what you give it. An incomplete history gives false frequencies.
- The categories it proposes are generic: compare them with your context and your data.
- Verify any figure or reference it puts forward: they may be invented.
- Anonymize incident exports and do not paste confidential data into an unauthorized tool.
Limits#
- Relying on what we remember is often effective: in a stable environment, the available cases really do reflect the most frequent ones. The bias appears when ease of recall has a source other than frequency.
- A vivid, rare event may deserve disproportionate attention: severity matters as much as probability (data loss, a death). Serious risks must not be ignored on the grounds that they are rare.
- Gigerenzer's causal link between the attacks and the rise in road deaths is an estimate, and it has been debated; the mechanism (the vivid risk diverts people toward a lesser perceived risk) remains well established.
- The effect depends on how the question is asked: asking for examples before the estimate, or asking for many of them, can reverse the judgment (work by Schwarz and colleagues, 1991, on experienced ease).
Sources and verification#
- Tversky & Kahneman (1973), "Availability: A heuristic for judging frequency and probability", Cognitive Psychology, 5(2)
- Tversky & Kahneman (1974), "Judgment under Uncertainty: Heuristics and Biases", Science
- Lichtenstein, Slovic, Fischhoff, Layman & Combs (1978), "Judged frequency of lethal events", Journal of Experimental Psychology: Human Learning and Memory, 4(6)
- Gigerenzer (2004), "Dread risk, September 11, and fatal traffic accidents", Psychological Science, 15(4)
- Gigerenzer (2006), "Out of the frying pan into the fire: Behavioral reactions to terrorist attacks", Risk Analysis, 26(2)
- Schwarz, Bless, Strack, Klumpp, Rittenauer-Schatka & Simons (1991), "Ease of retrieval as information: Another look at the availability heuristic", Journal of Personality and Social Psychology, 61(2)
- Kahneman (2011), Thinking, Fast and Slow, Farrar, Straus and Giroux.
See also#
Related biases#
Variants or cousins: not to be confused.
Counterweights and related reflexes#
What neutralises it.
- Les données chiffrées et l'historique (concept or method, no page)
- La liste de risques établie à froid (pré-mortem) (concept or method, no page)
- Reference class forecasting
